
Trained AI: Building Intelligent Systems in 2026
Artificial intelligence has evolved from theoretical concept to practical business tool, yet understanding how these systems actually work remains elusive for many professionals. At the heart of every AI application lies a trained AI system-a model that has learned patterns from data to perform specific tasks. Whether you're evaluating AI solutions for your organisation or ensuring compliance with emerging regulations like the EU AI Act, grasping the fundamentals of how AI systems are trained becomes essential. This knowledge empowers you to make informed decisions about implementation, governance, and risk management in an increasingly AI-driven workplace.
The Foundation of Trained AI Systems
A trained AI begins its life as an untrained model-essentially a mathematical framework with randomly initialised parameters that cannot perform useful tasks. Through exposure to relevant data and iterative adjustments, this framework gradually develops the ability to recognise patterns, make predictions, or generate content.
The training process involves feeding the model labelled examples that demonstrate the desired behaviour. For instance, a language model receives vast quantities of text, whilst an image recognition system processes millions of tagged photographs. Each iteration allows the model to adjust its internal parameters, reducing errors and improving accuracy.
Key Components of AI Training
The creation of a trained AI system requires several critical elements working in concert:
Training data: Large datasets that represent the problem domain comprehensively
Model architecture: The structural design determining how the AI processes information
Training algorithms: Mathematical methods that adjust model parameters to reduce errors
Computational resources: Processing power to handle millions or billions of calculations
Validation mechanisms: Systems to test performance and prevent overfitting
Quality matters immensely in training data. Biased, incomplete, or inaccurate datasets produce trained AI systems that perpetuate those flaws, potentially leading to discriminatory outcomes or unreliable predictions.
Types of Trained AI Models
Different tasks require distinct training approaches. Understanding these categories helps organisations select appropriate AI solutions and assess their capabilities accurately.
Supervised learning produces trained AI systems that excel at classification and prediction tasks. These models learn from labelled examples where the correct answer is known. Customer service chatbots, fraud detection systems, and medical diagnostic tools typically employ supervised learning.
Unsupervised learning creates trained AI that discovers hidden patterns without predefined labels. Clustering algorithms group similar data points, whilst anomaly detection identifies outliers. Marketing teams use these models for customer segmentation, whilst cybersecurity applications detect unusual network behaviour.
Reinforcement learning trains AI through trial and error, rewarding successful actions and penalising mistakes. This approach has produced remarkable results in game-playing AI and robotics, where the system learns optimal strategies through repeated interactions with an environment.
Comparison of Training Approaches
Training Type | Data Requirements | Common Applications | Complexity Level |
Supervised | Labelled datasets | Classification, regression | Moderate |
Unsupervised | Unlabelled data | Clustering, compression | High |
Reinforcement | Reward signals | Robotics, gaming | Very high |
Transfer learning | Pre-trained models + small datasets | Specialised tasks | Low to moderate |
Transfer learning deserves special mention as an increasingly popular method. Rather than training from scratch, organisations adapt existing trained AI models to new tasks, dramatically reducing time and resource requirements.
Training Large Language Models
The trained AI systems capturing public attention in 2026-conversational assistants, content generators, and code writing tools-are predominantly large language models. These sophisticated systems require extraordinary computational resources and innovative training techniques.
Foundation models like GPT-4 and Claude undergo multi-stage training processes. Initial pre-training exposes the model to trillions of words from books, websites, and documents, teaching it language structure, factual knowledge, and reasoning patterns. This phase alone may consume months of processing time across thousands of specialised processors.
Subsequent fine-tuning refines behaviour for specific applications. Reinforcement learning from human feedback (RLHF) has become standard practice, where human evaluators rank model outputs, and these preferences guide further training. This creates trained AI that aligns more closely with human values and produces more helpful, harmless responses.
Quality Control in AI Training
Ensuring trained AI systems perform reliably requires rigorous validation throughout development:
Data auditing: Reviewing training data for biases, errors, and representation gaps
Performance benchmarking: Testing against standardised datasets to measure capabilities
Adversarial testing: Deliberately attempting to trigger unwanted behaviours
Continuous monitoring: Tracking model performance after deployment to detect degradation
Version control: Maintaining records of training data, parameters, and model iterations
Organisations subject to the EU AI Act must implement these quality control measures systematically. The regulation mandates transparency about training processes, data sources, and model limitations-particularly for high-risk AI systems.
Practical Considerations for Organisations
Deploying trained AI in enterprise environments introduces challenges beyond technical performance. Governance frameworks must address data privacy, intellectual property, bias mitigation, and regulatory compliance.
Data governance becomes paramount. Training AI often requires access to sensitive information-customer records, financial data, or proprietary documents. Organisations must establish clear policies about what data can be used for training, how it should be anonymised, and who maintains oversight.
Model documentation supports both internal understanding and regulatory compliance. Comprehensive records should detail training data sources, pre-processing steps, model architecture choices, hyperparameter settings, and validation results. This transparency enables audits and helps identify potential issues before they cause harm.
For professionals seeking to understand these complex systems, AI literacy training provides essential foundations. Courses aligned with Article 4 of the EU AI Act ensure employees grasp not just technical concepts but also governance requirements and risk management principles.
Resource Requirements for Training AI
Model Scale | Training Time | Computational Cost | Typical Applications |
Small (millions of parameters) | Hours to days | £500-£5,000 | Specific classification tasks |
Medium (hundreds of millions) | Days to weeks | £10,000-£100,000 | Industry-specific models |
Large (billions) | Weeks to months | £1M-£10M | General-purpose foundation models |
Very large (trillions) | Months | £50M+ | Cutting-edge research models |
Most organisations benefit more from adapting existing trained AI rather than building from scratch. Cloud platforms offer pre-trained models for common tasks, reducing costs and accelerating deployment.
Emerging Trends in AI Training
The field continues evolving rapidly, with several developments reshaping how trained AI systems are created and deployed.
Federated learning enables training across distributed datasets without centralising sensitive information. Healthcare organisations can collaboratively improve diagnostic models whilst keeping patient data local. This approach addresses privacy concerns whilst expanding training data diversity.
Few-shot learning creates trained AI that generalises from minimal examples. Rather than requiring thousands of labelled instances, these models adapt to new tasks with just a handful of demonstrations. This dramatically reduces data collection costs and enables rapid customisation.
Constitutional AI embeds ethical principles directly into the training process. Models learn to refuse harmful requests, provide balanced perspectives, and acknowledge uncertainty-not through post-hoc filtering but through fundamental training objectives.
Tools like CriticGPT represent another frontier: trained AI systems that help improve other AI systems by identifying subtle errors human reviewers might miss. This creates feedback loops that accelerate quality improvements across the AI ecosystem.
Skills for Working with Trained AI
Professionals interacting with AI systems need conceptual understanding rather than deep technical expertise. Knowing what questions to ask proves more valuable than understanding backpropagation algorithms.
Critical evaluation skills help assess trained AI capabilities honestly. Can this model handle edge cases? What happens when input data differs from training data? Where might biases emerge? Asking these questions prevents over-reliance on flawed systems.
Prompt engineering maximises value from language model trained AI. Well-crafted instructions dramatically improve output quality, whilst poor prompts waste time and resources. This skill combines understanding of model capabilities with clear communication.
Integration planning connects AI capabilities to business processes effectively. Which tasks benefit most from automation? Where does human judgment remain essential? How should exceptions be handled? Answering these questions ensures trained AI enhances rather than disrupts operations.
The AI Literacy Course for EU AI Act Compliance addresses these practical needs, equipping teams with frameworks for responsible AI adoption across organisations of all sizes.
Training Data Challenges and Solutions
The adage "garbage in, garbage out" applies emphatically to trained AI. Poor quality training data produces unreliable models, regardless of sophisticated algorithms or massive computational budgets.
Bias in training data manifests in multiple forms. Historical data may reflect discriminatory practices. Sampling methods might under-represent certain populations. Labelling processes could encode subjective judgments as objective truth. Each introduces systematic errors into trained AI behaviour.
Mitigation strategies include:
Diverse data collection ensuring representation across relevant categories
Bias auditing using statistical methods to detect disparate impacts
Balanced datasets preventing over-fitting to majority groups
Regular retraining incorporating new data and correcting identified issues
Human-in-the-loop processes maintaining oversight on critical decisions
Data privacy presents another significant challenge. Training often requires large datasets, yet regulations like GDPR restrict how personal information can be used. Synthetic data generation offers one solution, creating artificial examples that preserve statistical properties without exposing real individuals. Differential privacy techniques add mathematical noise during training, protecting individual privacy whilst maintaining model utility.
Intelligent Agents and Autonomous Systems
Beyond static models, trained AI powers intelligent agents that perceive environments and take actions to achieve goals. These systems combine multiple trained models with decision-making frameworks and interaction capabilities.
Autonomous vehicles exemplify this complexity. Multiple trained AI systems handle object detection, path planning, traffic sign recognition, pedestrian behaviour prediction, and obstacle avoidance-all coordinated through higher-level decision-making logic.
Virtual assistants similarly integrate speech recognition trained AI, natural language understanding models, task-specific knowledge bases, and response generation systems. Each component requires separate training, yet they must function cohesively to deliver useful service.
Research institutions like the Beijing Academy of Artificial Intelligence advance these capabilities, exploring how trained AI systems can collaborate, learn continuously, and adapt to novel situations beyond their training scenarios.
Training Multimodal AI Systems
Modern applications increasingly combine different data types-text, images, audio, and structured data-requiring multimodal trained AI.
Text-to-image models demonstrate this approach, learning relationships between language descriptions and visual content. Training requires paired datasets where images are annotated with detailed captions, teaching the model how concepts translate across modalities.
These systems enable creative applications but also raise new governance questions. Can trained AI generate copyrighted characters? Who owns AI-created artwork? How should misleading synthetic media be detected and labelled? Organisations deploying multimodal trained AI must address these considerations proactively.
Risk Management for Trained AI
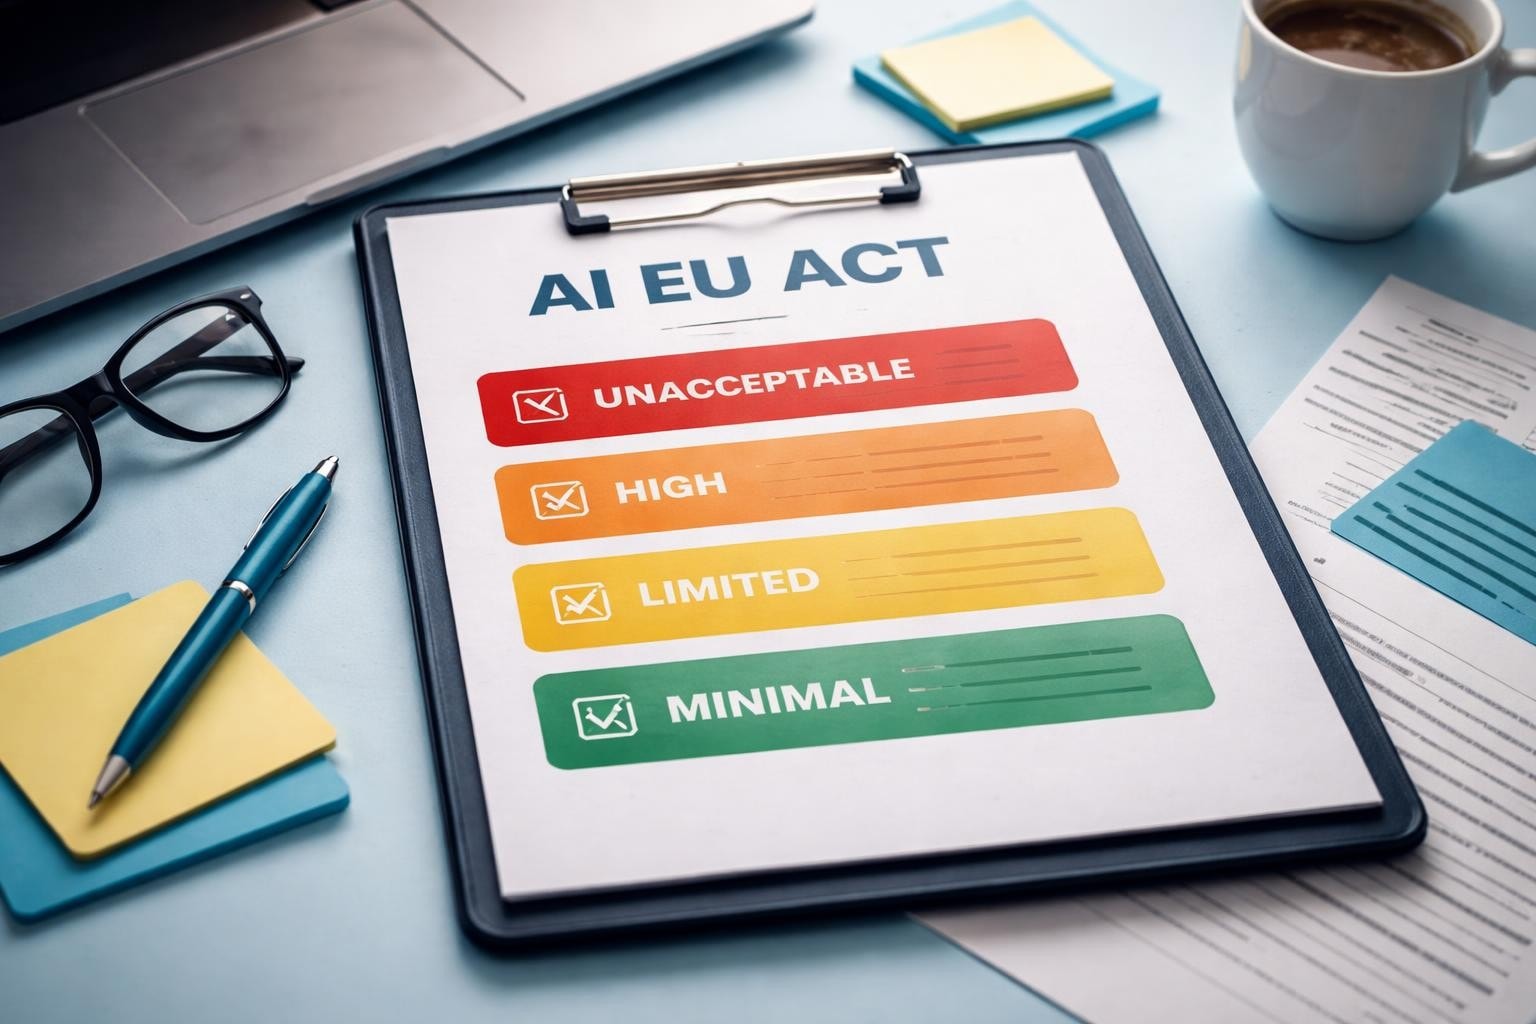
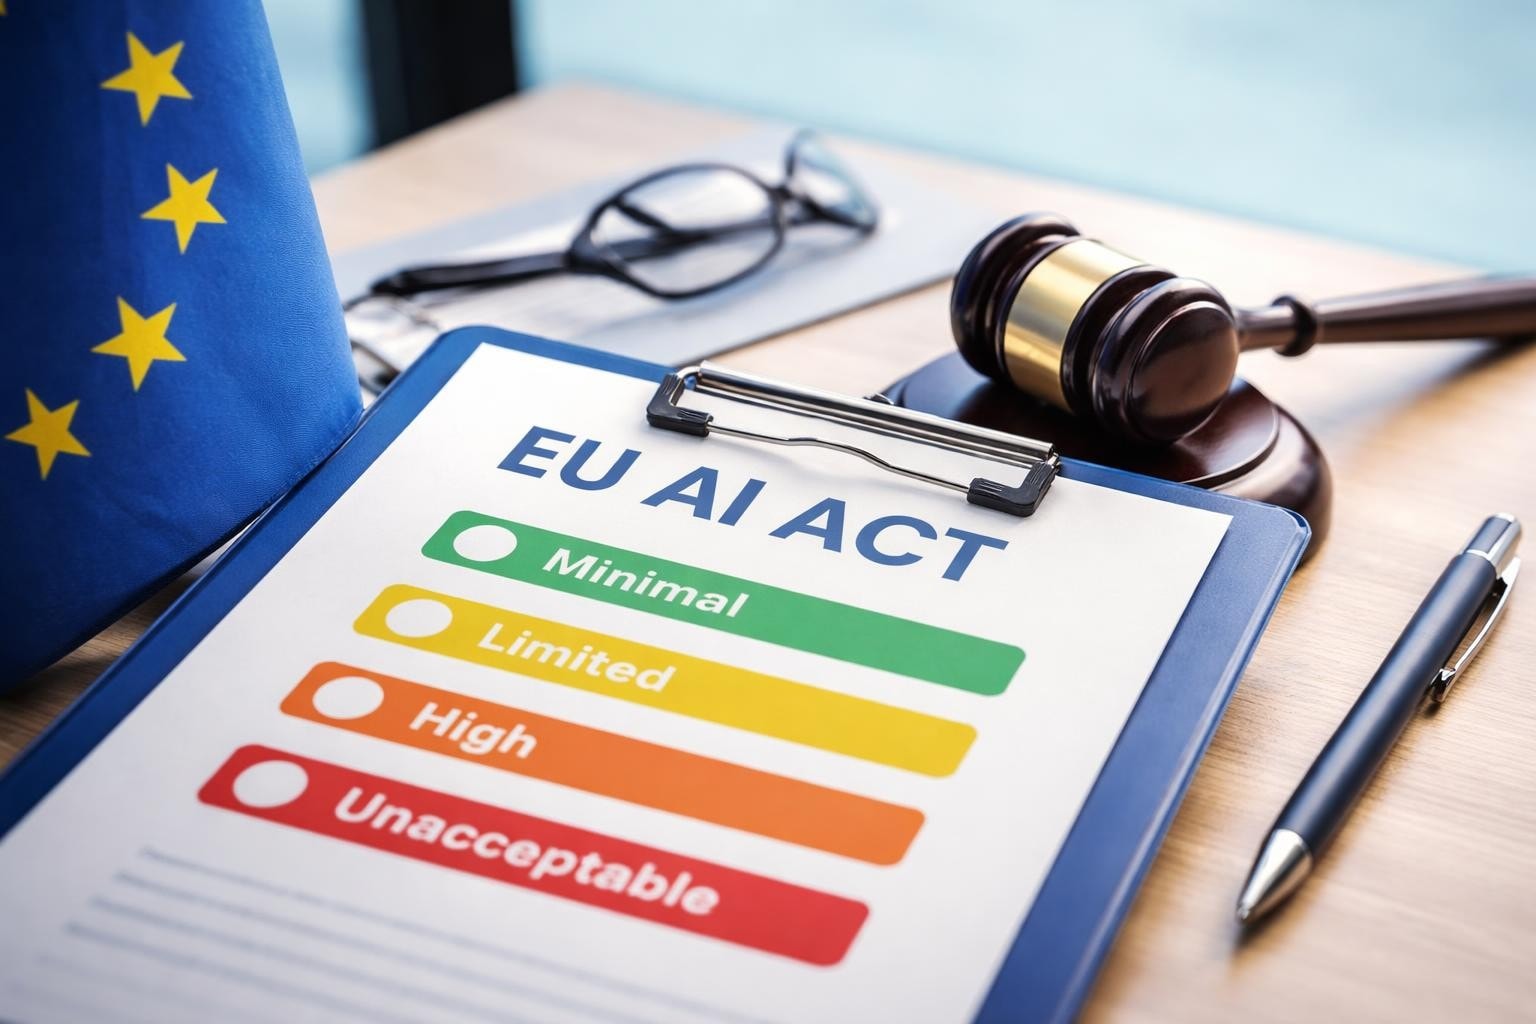
The EU AI Act categorises AI systems by risk level, with requirements scaling accordingly. High-risk applications demand extensive documentation, testing, and human oversight. Prohibited uses-such as social scoring or manipulative techniques-are banned outright.
Risk assessment frameworks help organisations classify their trained AI deployments appropriately. Factors include:
Application domain (healthcare, finance, employment, law enforcement)
Decision autonomy (advisory vs. automated action)
Impact severity (reversible vs. irreversible consequences)
Affected population (individuals vs. groups, vulnerable populations)
Transparency requirements (explainability needs, contestability provisions)
Conformity assessment procedures verify that high-risk trained AI meets regulatory standards before deployment. Third-party auditors may review training data quality, bias testing results, performance metrics, and risk mitigation measures.
Post-market monitoring continues after deployment. Trained AI systems can degrade over time as input data distributions shift. Regular retraining, performance tracking, and incident reporting maintain compliance and reliability.
Building AI Literacy Across Organisations
Successful AI adoption requires workforce-wide understanding, not just technical specialists. When employees grasp how trained AI works, they make better decisions about when to use it, how to interpret outputs, and where human judgment remains essential.
Education programmes should cover core concepts: how models learn from data, what limitations exist, where biases emerge, and which regulations apply. Interactive formats engaging learners through practical scenarios prove more effective than passive lectures.
Multilingual delivery ensures accessibility across diverse workforces. The same core principles apply regardless of language, yet effective learning requires communication in each employee's preferred language.
Self-paced formats accommodate varying schedules and learning speeds. Professionals can engage with material during available time rather than coordinating synchronous sessions across time zones and responsibilities.
Understanding how trained AI systems work-from data preparation through deployment-empowers organisations to harness these powerful tools responsibly and effectively. Whether you're evaluating vendor solutions, implementing internal AI capabilities, or ensuring regulatory compliance, foundational knowledge of training processes, data requirements, and risk management principles proves essential. Building this capability across your workforce positions your organisation for success in an AI-augmented future. GURO (myaitraining.eu) delivers comprehensive AI literacy training aligned with EU AI Act requirements, available in over 30 languages and designed for practical, self-paced learning that builds confidence and competence across your entire organisation.
Comments