
Training an AI: Essential Principles for 2026
Training an AI system has evolved from a niche technical exercise into a fundamental business capability. Whether you're developing customer service chatbots, predictive analytics tools, or compliance monitoring systems, understanding the principles behind AI training determines the difference between a reliable tool and a liability. In 2026, organisations face increasing scrutiny over how their AI systems are trained, particularly within regulatory frameworks like the EU AI Act. This guide explores the essential components, methodologies, and considerations that shape effective AI training processes.
Understanding the Fundamentals of AI Training
Training an AI involves teaching algorithms to recognize patterns, make predictions, or generate outputs based on data. The process mirrors how humans learn from experience, but with distinct differences in scale, speed, and methodology.
At its core, AI training requires three essential components: quality data, appropriate algorithms, and robust validation mechanisms. The data serves as the foundation from which the system learns, whilst algorithms provide the mathematical framework for processing that information. Validation ensures the trained model performs reliably across different scenarios.
The Role of Data in AI Training
Data quality directly impacts AI performance. Training an AI with biased, incomplete, or inaccurate datasets produces systems that replicate those flaws at scale.
Consider these critical data characteristics:
Relevance: Data must align with the tasks the AI will perform
Diversity: Datasets should represent varied scenarios and edge cases
Accuracy: Information must be verified and free from systematic errors
Volume: Sufficient examples enable the model to generalise effectively
Recency: Current data prevents outdated pattern recognition
Modern AI training increasingly focuses on establishing data trusts and democratizing access to quality training datasets, particularly for organizations without massive proprietary data reserves.
Selecting Training Methodologies
Different AI applications require distinct training approaches. Understanding these methodologies helps organizations choose the right path for their specific needs.
Methodology | Best For | Data Requirements | Training Time |
Supervised Learning | Classification, prediction | Labelled datasets | Moderate |
Unsupervised Learning | Pattern discovery | Unlabelled data | Variable |
Reinforcement Learning | Decision-making | Reward signals | Extensive |
Transfer Learning | Limited data scenarios | Pre-trained models | Reduced |
Supervised learning remains the most common approach for business applications. This method involves training an AI on labelled examples where the correct output is known. For instance, a fraud detection system learns from historical transactions marked as legitimate or fraudulent.
Unsupervised learning proves valuable when you lack labelled data but want to discover hidden patterns. Organisations use this approach for customer segmentation, anomaly detection, and exploratory data analysis.
Transfer Learning and Fine-Tuning
Rather than training an AI from scratch, transfer learning leverages pre-trained models and adapts them to specific tasks. This approach dramatically reduces the data, time, and computational resources required.
Fine-tuning involves taking a foundation model trained on broad datasets and specializing it for particular applications. A general language model might be fine-tuned on legal documents to create a contract analysis tool, or on medical literature to assist with diagnostic support.
The rise of foundation models has made transfer learning the preferred approach for many organizations. However, this strategy introduces dependencies on the quality and biases present in the original training data.
Data Collection and Preparation Strategies
Successful AI training begins long before algorithms process data. The collection and preparation phases determine whether your model can achieve reliable performance.
Sourcing Authoritative Data
Training an AI with authoritative sources reduces the risk of misinformation and unreliable outputs. Research emphasizes the importance of using verified, authoritative data sources to improve AI quality and accuracy.
Organizations should establish clear criteria for data sources:
Verify publisher credibility through reputation checks and peer review status
Assess data provenance to understand collection methodologies
Evaluate temporal relevance ensuring information reflects current conditions
Check licensing permissions to avoid copyright violations
Document all sources maintaining full audit trails
The legal and ethical considerations of using copyrighted materials in AI training continue to evolve, making proper licensing and fair use assessments essential.
Data Cleaning and Preprocessing
Raw data rarely arrives in a format suitable for training an AI. Preprocessing transforms messy real-world information into structured inputs that algorithms can process effectively.
Common preprocessing steps include removing duplicates, handling missing values, normalizing scales, encoding categorical variables, and balancing class distributions. Each decision during this phase impacts model behavior.
For example, if you're training an AI for hiring decisions and your historical data over-represents certain demographics, the model will learn those imbalances as patterns. Preprocessing must address such biases explicitly.
Training Process and Optimization
Once data is prepared, the actual training process involves iterative cycles of learning and adjustment. Training an AI is rarely a linear process but rather an experimental journey requiring patience and systematic evaluation.
Model Architecture Selection
Choosing the right model architecture depends on your problem type, data characteristics, and performance requirements. Neural networks excel at image and language tasks, whilst decision trees often perform better for tabular business data with clear feature relationships.
Key architectural considerations:
Input data format and dimensionality
Computational resources available for training
Interpretability requirements for regulatory compliance
Deployment environment constraints
Real-time performance expectations
The EU AI Act's Article 4 requirements emphasize transparency and accountability, making architectural choices that support explainability increasingly important for European organizations.
Hyperparameter Tuning
Beyond the core architecture, hyperparameters control how the training process unfolds. Learning rates, batch sizes, regularization strengths, and network depths all influence final model performance.
Systematic tuning approaches include grid search, random search, and Bayesian optimization. Each method explores the hyperparameter space differently, balancing thoroughness against computational cost.
Modern AutoML platforms automate much of this process, but understanding the underlying principles remains valuable for diagnosing problems and optimizing results.
Validation and Testing Frameworks
Training an AI without rigorous validation produces overconfident systems that fail in real-world conditions. Proper testing separates training data from validation and test sets, preventing models from simply memorizing examples.
Cross-Validation Techniques
K-fold cross-validation divides data into multiple subsets, training on some whilst testing on others. This approach provides more robust performance estimates than single train-test splits, particularly when working with limited data.
For time-series applications, temporal cross-validation maintains chronological order, training on historical data and testing on future periods. This prevents data leakage where future information inappropriately influences predictions.
Validation Metric | Measures | Best For |
Accuracy | Overall correctness | Balanced datasets |
Precision | True positive rate | Minimizing false positives |
Recall | Coverage of positives | Minimizing false negatives |
F1 Score | Harmonic mean | Imbalanced classes |
AUC-ROC | Discrimination ability | Binary classification |
Detecting and Mitigating Overfitting
Overfitting occurs when training an AI produces a model that performs brilliantly on training data but poorly on new examples. The system has memorized specific instances rather than learning generalizable patterns.
Regularization techniques like L1 and L2 penalties, dropout layers, and early stopping help prevent overfitting. Monitoring both training and validation metrics throughout the process reveals when overfitting begins.
Addressing Bias and Fairness
Training an AI inherently involves making choices about what patterns matter and which to ignore. These decisions embed values and priorities into systems that may affect millions of users.
Identifying Sources of Bias
Bias enters AI systems through multiple pathways. Historical bias exists in past data that reflects discriminatory practices. Representation bias occurs when training data doesn't adequately cover all relevant populations. Measurement bias stems from how we define and quantify outcomes.
Organisations must actively audit training data and model outputs for disparate impacts across demographic groups. This process should occur before deployment and continue throughout the system's operational life.
Fairness Constraints and Debiasing
Several technical approaches help reduce bias when training an AI. Reweighting samples gives underrepresented groups greater influence during training. Adversarial debiasing introduces objectives that penalize discriminatory patterns. Post-processing adjustments modify outputs to satisfy fairness criteria.
However, technical fixes alone prove insufficient. The Trusted Educational AI Standard emphasizes the importance of combining technical rigor with pedagogical soundness and ethical oversight throughout the AI development lifecycle.
Advanced Training Techniques
As AI systems grow more sophisticated, training methodologies continue to evolve. Understanding emerging approaches helps organizations stay competitive whilst managing complexity.
Retrieval Augmented Generation
Rather than relying solely on patterns learned during training, RAG systems augment AI responses with information retrieved from external sources. Research demonstrates how RAG improves accuracy by grounding outputs in authoritative references, reducing hallucinations and improving reliability.
This approach proves particularly valuable for applications requiring current information or domain-specific knowledge. Training an AI with RAG capabilities involves teaching the system both to generate responses and to identify when external retrieval would improve accuracy.
Few-Shot and Zero-Shot Learning
Traditional supervised learning requires thousands or millions of labelled examples. Few-shot learning enables systems to perform tasks with minimal examples, whilst zero-shot learning attempts tasks without specific training examples at all.
These capabilities emerge from training large foundation models on diverse data, then prompting them strategically for specific tasks. Organizations can leverage these approaches to deploy AI solutions faster, though they sacrifice some task-specific optimization.
Continuous Learning and Model Updates
Training an AI is not a one-time event. Deployed systems must adapt to changing conditions, evolving user needs, and shifting data distributions.
Monitoring for Data Drift
Data drift occurs when the statistical properties of input data change over time. A model trained on 2024 customer behavior may perform poorly in 2026 if preferences and patterns have shifted.
Effective monitoring tracks:
Input feature distributions comparing current data to training data
Prediction confidence levels identifying uncertainty patterns
Actual outcomes measuring real-world performance
User feedback capturing qualitative issues
Edge cases documenting failure modes
Retraining Strategies
When drift degrades performance, retraining becomes necessary. Organizations must balance the cost of retraining against the risk of degraded performance.
Periodic retraining follows a fixed schedule, regardless of performance changes. Triggered retraining responds to specific performance thresholds or drift metrics. Continuous learning updates models incrementally as new data arrives.
Each approach carries trade-offs between freshness, stability, and resource consumption. Mission-critical systems often employ hybrid strategies combining scheduled updates with performance-triggered interventions.
Compliance and Documentation Requirements
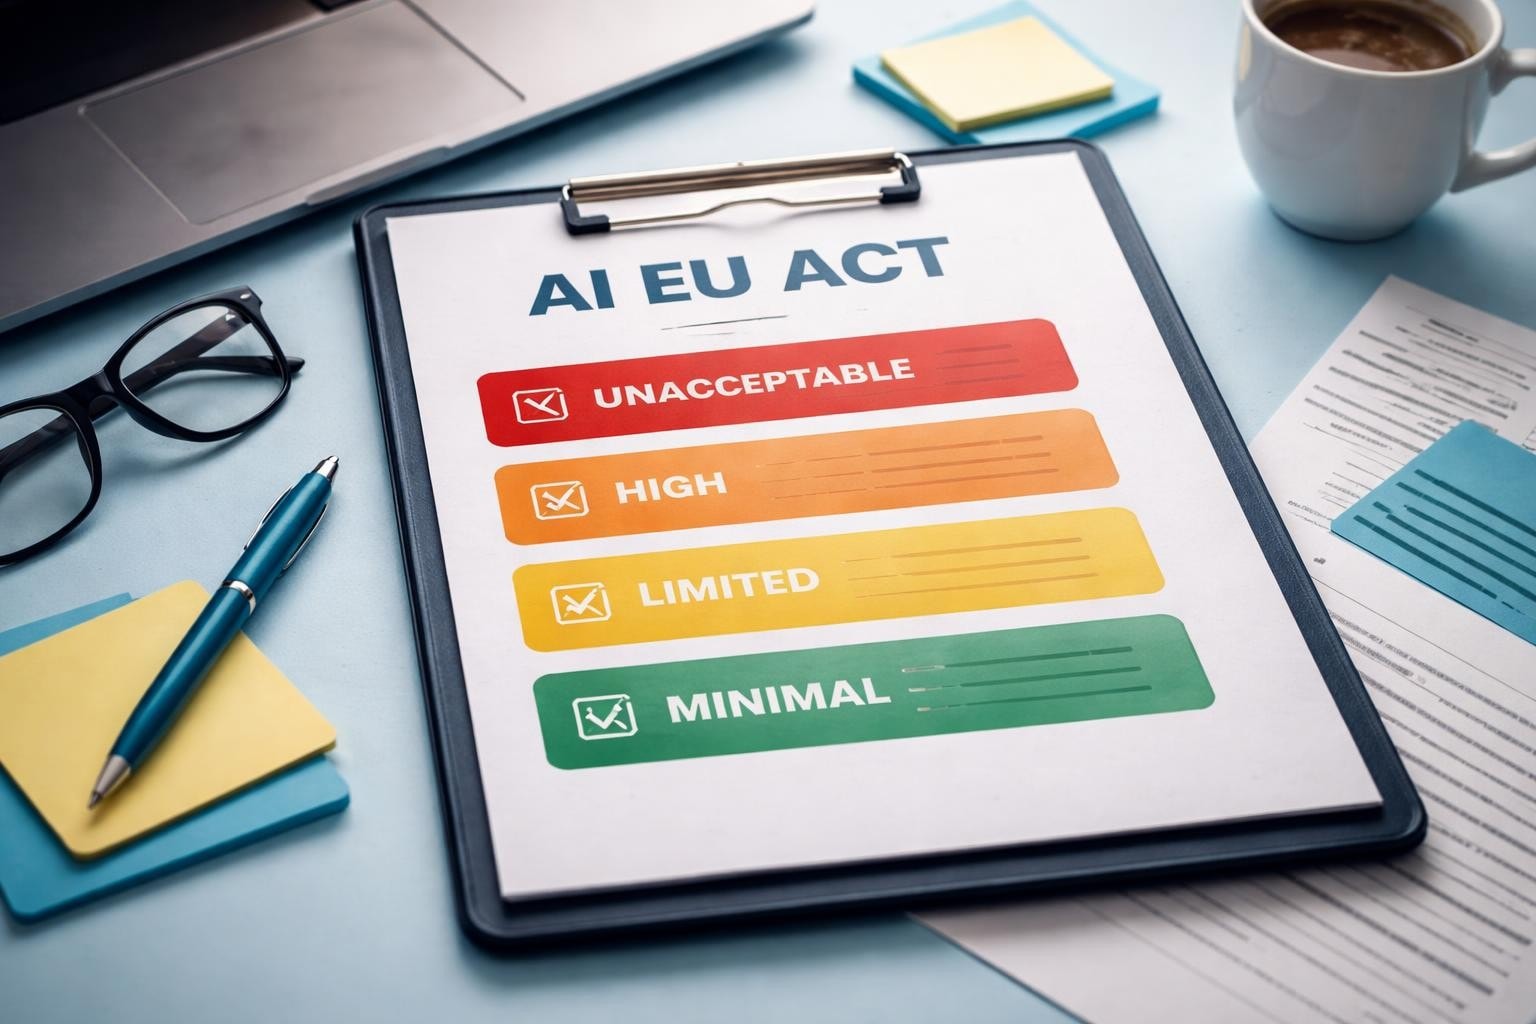
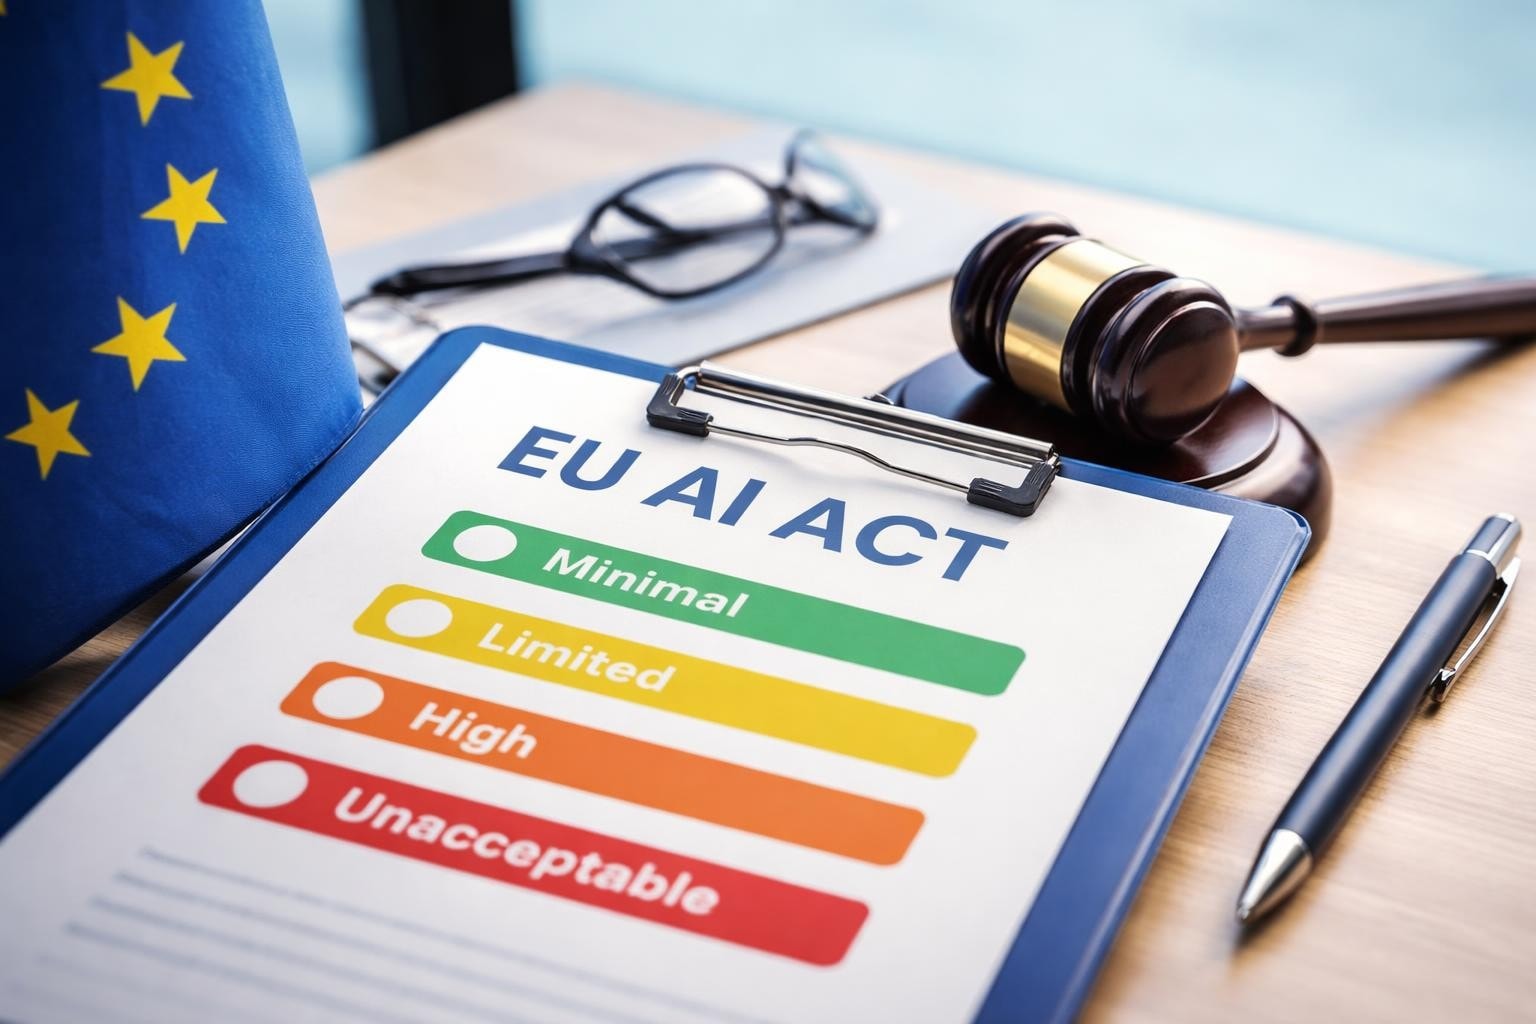
Training an AI under the EU AI Act requires comprehensive documentation demonstrating compliance with transparency, accountability, and safety requirements.
Organizations subject to Article 4 must document training data sources, preprocessing decisions, model architectures, validation results, and bias mitigation efforts. This documentation proves essential during audits and investigations.
For businesses seeking to ensure their workforce understands these requirements, AI Literacy Course for EU AI Act Compliance provides structured education aligned with regulatory expectations. Proper training ensures teams can develop, deploy, and maintain AI systems whilst meeting legal obligations.
Creating Audit Trails
Comprehensive audit trails document every decision in the AI training pipeline. Version control systems track data changes, experiment logs record hyperparameter trials, and model registries maintain deployment histories.
These records serve multiple purposes beyond compliance. They enable reproducibility for scientific validation, support debugging when issues emerge, and facilitate knowledge transfer as team members change.
Resource Requirements and Infrastructure
Training an AI demands significant computational resources, particularly for large models and extensive datasets. Organizations must balance performance requirements against infrastructure costs.
Resource Type | Impact on Training | Optimization Strategies |
GPU/TPU compute | Training speed | Batch size tuning, mixed precision |
Memory | Model size capacity | Gradient checkpointing, model sharding |
Storage | Dataset accessibility | Data compression, efficient formats |
Network bandwidth | Distributed training | Data locality, compression |
Cloud platforms offer scalable infrastructure that adjusts to training workloads, whilst on-premises solutions provide greater control and potentially lower long-term costs for consistent usage patterns.
Modern MLOps practices automate infrastructure provisioning, experiment tracking, and model deployment, reducing the operational burden of training and maintaining AI systems at scale.
Ethical Considerations and Stakeholder Impact
Beyond technical and legal requirements, training an AI involves ethical responsibilities to users, affected communities, and society broadly.
Impact Assessments
Before training an AI for deployment, organizations should conduct impact assessments evaluating potential harms. These assessments consider who benefits from the system, who bears risks, and how power dynamics might shift.
Questions to address include:
Could this system amplify existing inequalities?
What happens when the AI makes mistakes?
Who can challenge or appeal AI decisions?
How transparent is the system's operation?
What recourse exists for those harmed?
Current research highlights hidden risks in generative AI, emphasizing the need for careful scrutiny of foundation models and their training processes.
Stakeholder Engagement
Involving affected stakeholders in AI development improves both technical performance and social legitimacy. Users can identify edge cases engineers miss, domain experts can validate outputs, and community representatives can highlight potential harms.
This engagement should begin during the planning phase, continue through training and testing, and extend into deployment and monitoring. Building feedback mechanisms into systems allows continuous improvement based on real-world experience.
Measuring Training Success
Training an AI successfully requires clear success criteria established before development begins. These metrics should align with business objectives whilst incorporating safety and fairness considerations.
Performance Metrics
Technical performance metrics measure how accurately the AI completes its intended task. Precision, recall, accuracy, and domain-specific measures provide quantitative assessments of capability.
However, maximizing these metrics alone proves insufficient. A highly accurate model that occasionally produces catastrophic errors may be less valuable than a slightly less accurate but more robust alternative.
Business Impact Metrics
Ultimately, training an AI should deliver measurable business value. Cost savings, revenue increases, efficiency gains, and risk reductions provide concrete evidence of success.
These metrics require careful baseline establishment and controlled deployment to distinguish AI impact from confounding factors. A/B testing, phased rollouts, and longitudinal tracking help isolate AI contributions.
Building Organizational Capability
Successfully training an AI requires more than technical expertise. Organizations need interdisciplinary teams, appropriate governance structures, and cultures that support responsible innovation.
Team Composition
Effective AI teams combine data scientists, domain experts, engineers, ethicists, and business stakeholders. This diversity ensures technical feasibility aligns with practical utility and ethical responsibility.
Cross-functional collaboration during training prevents siloed development that produces technically sophisticated systems lacking real-world applicability. Regular communication and shared accountability mechanisms support this collaboration.
Knowledge Sharing and Documentation
As AI systems grow more complex, organizational knowledge becomes a critical asset. Documentation standards, code repositories, and experiment tracking systems preserve insights and enable knowledge transfer.
For organizations building AI literacy across their workforce, comprehensive educational programmes ensure everyone understands fundamental concepts, regulatory requirements, and ethical considerations. GURO provides resources designed specifically for this purpose, supporting teams in developing shared AI competencies.
Training an AI effectively requires balancing technical sophistication with ethical responsibility, regulatory compliance, and practical business value. As AI systems become increasingly central to organizational operations, building internal capability to develop, deploy, and maintain these systems responsibly becomes essential. GURO (myaitraining.eu) offers AI literacy courses aligned with EU AI Act requirements, providing your team with the foundational knowledge needed to navigate this complex landscape confidently. Explore our interactive, multilingual courses designed for practical application in your organization.
Comments